The AWS Bahrain Outage Nobody's DR Plan Was Ready For
AWS just told customers it can't recover data lost when regional infrastructure damage exceeded what its resiliency design was built to survive. Here's what 'regional redundancy' actually promises, and what it doesn't.

In this article 5 sections
Quick answer: AWS confirmed on September 15 that it cannot restore customer data and resources in its Middle East (Bahrain) region or one availability zone of its UAE region, after infrastructure damage exceeded what the platform's regional and multi-AZ resiliency was built to withstand. If your DR plan assumes a "region" is a single unit of failure that AWS will always eventually bring back, this is the event that proves that assumption wrong. The fix isn't switching clouds. It's testing what your own architecture actually does when a whole region stays down for good.
Getting paged at 3 a.m. because a "highly available" setup turned out to be one database server with a hopeful name is a familiar story in IT. So when a hyperscaler with AWS's engineering budget says a region is gone for good, that's worth an actual read, not a shrug and a "well, that's Bahrain, not us." At Protocol Wire, we cover AI, software, startups and the infrastructure underneath them.
Here's the short version: infrastructure damage in early 2026 hit multiple AWS facilities in the Middle East at once. AWS spent months trying to bring the Bahrain region and part of its UAE region back online. On September 15, it told customers, in plain language, that it's done trying. Data and resources hosted exclusively in those zones are gone.
What Actually Happened to AWS's Middle East Region
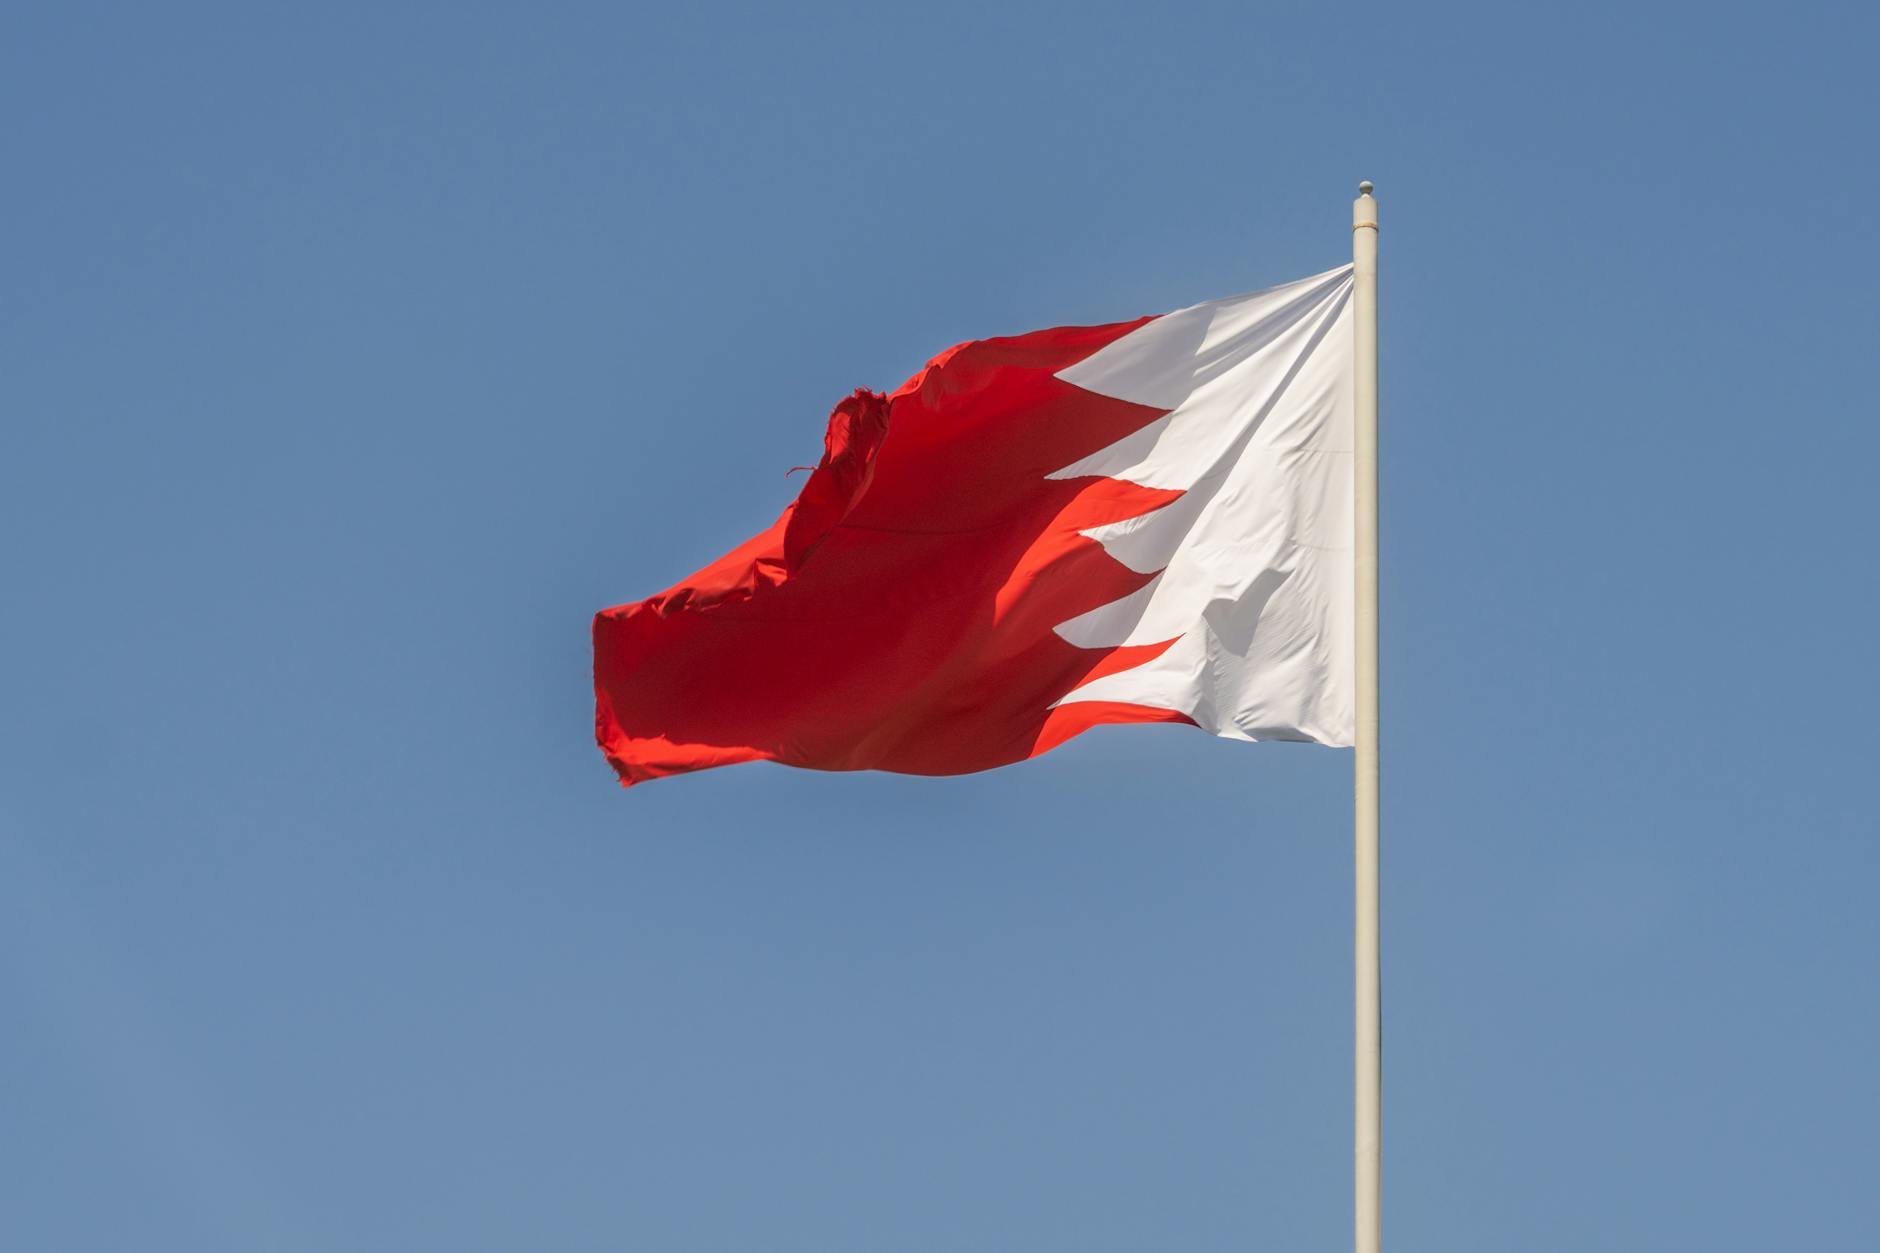
Strip out the geopolitics and you're left with an infrastructure story: physical facilities took structural damage across more than one availability zone at roughly the same time, which is exactly the scenario multi-AZ design is supposed to make survivable. It didn't, because the damage wasn't the kind of isolated, single-point failure that architecture is built around. AWS confirmed to reporters on September 15 that it can no longer restore customer data and resources hosted exclusively in the Bahrain region or the affected UAE zone. In its own updates, AWS said the damage to Bahrain "exceeded what our regional and multi-AZ services are designed to withstand," which is about as direct an admission as a hyperscaler ever puts in writing. Regional reporting on the incident noted that a second availability zone went down months after the initial damage, which is what eventually took the whole region offline rather than just one zone of it. That staggered failure is the part worth sitting with — this wasn't one bad day, it was a slow bleed that outlasted the redundancy built to absorb it.
Why Multi-AZ Didn't Save These Customers
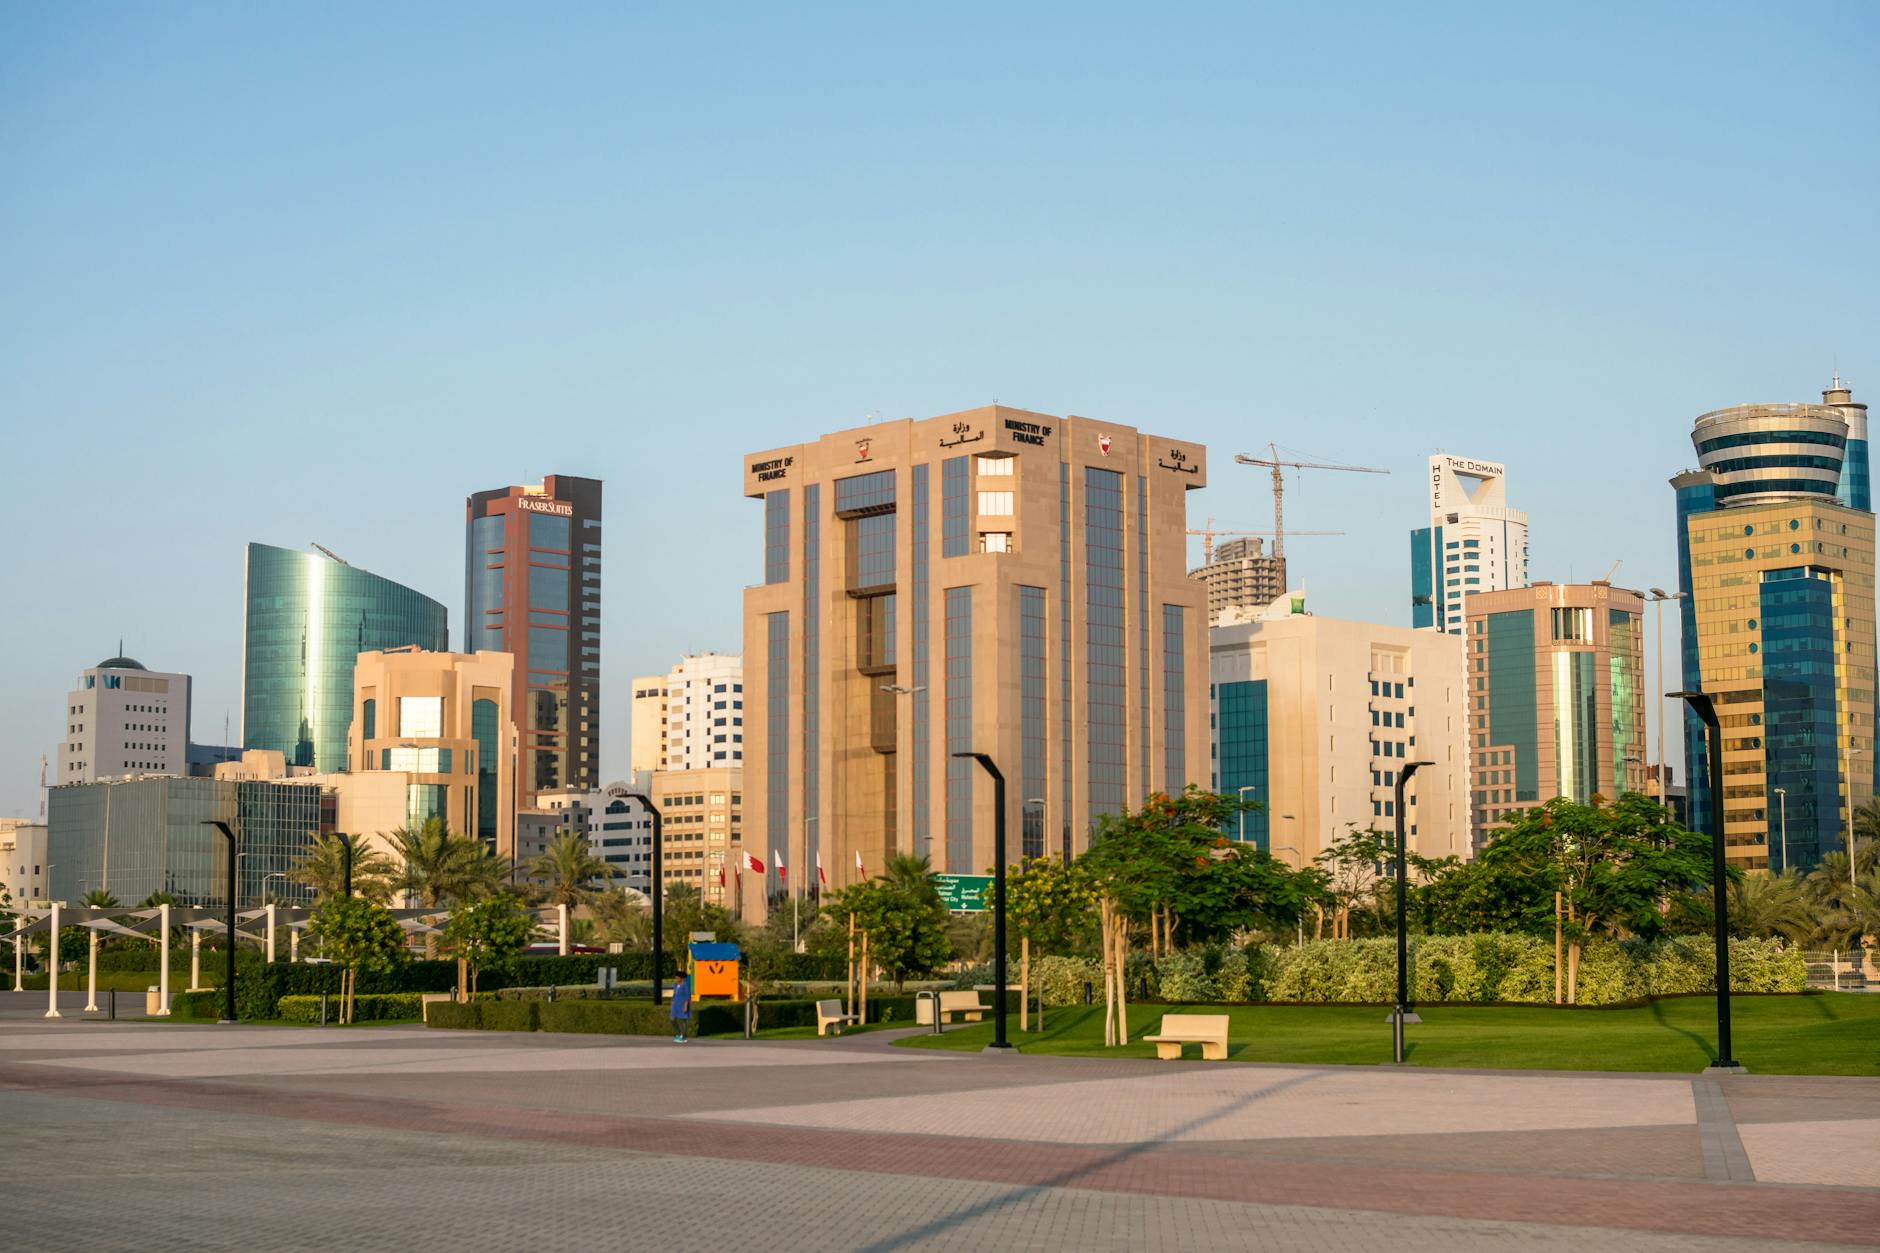
Every cloud vendor's marketing deck has a slide that says something like "99.99% availability, built on redundant, isolated Availability Zones." That's true, and it's also not the same promise as "your data survives a regional-scale event." An Availability Zone is a physically separate facility inside one region, connected by fast, dedicated fiber; a Region is a geographic collection of those zones. Per AWS's own resiliency model, the company is responsible for the resiliency of the cloud — the physical infrastructure — while you're responsible for resiliency in the cloud, meaning how you architect around it, per the shared responsibility model for resiliency AWS documents directly. Multi-AZ protects you against one facility going dark. It does nothing for you if the event takes out the region those facilities live in — which is exactly the scenario that happened here, and exactly the scenario most teams never actually test for, because it's rare, expensive to simulate, and "AWS has never lost a whole region before" felt like a safe enough bet. It wasn't.
Vendor renewal calls often go like this: someone asks about disaster recovery, gets pointed at a diagram with three colored boxes labeled "Region A," "Region B," and a dotted line between them, and everyone nods and moves on to pricing. Nobody asks what happens if the dotted line is doing more replication work than the failover plan assumes, or whether anyone has actually cut over to Region B in the last two years instead of just reading about it in a runbook. That gap between the diagram and the reality is exactly where this kind of loss happens. It's not a sophisticated failure mode. It's the same one that's been burning teams since long before cloud existed — the backup nobody tested, dressed up in better branding. Questions like these belong in any vendor review, including the kind laid out in a buyer's look at well-funded early-stage vendors before you sign.
The Checklist Most DR Plans Skip
Most DR documentation reads great and has never actually been run. Here's what to check this week, not next quarter:
- Cross-region replication, actually verified. Not "we enabled it in 2023." Pull a real object out of the secondary region today and confirm it's current.
- RTO/RPO numbers tied to a full-region loss, not a single-AZ blip. If your recovery time objective was written assuming AWS brings the region back in a few hours, rewrite it assuming it never comes back.
- Backups stored outside the primary provider entirely, for anything you genuinely cannot afford to lose. Redundancy inside one vendor's blast radius isn't the same as redundancy.
- A documented decision for what "acceptable data loss" actually means per system, signed off by someone who isn't you, so it's not a surprise mid-incident.
None of this is exotic. It's the boring stuff that gets skipped because it never seems urgent until the week it's the only thing that matters. Industry analysis on 2026 cloud reliability trends has been pointing out for a while now that outages at this scale are becoming a recurring cost of doing business with hyperscalers stretched thin by AI infrastructure demand, not a freak event — so treat the checklist as maintenance, not a one-time project. The same logic applies to contract exit terms, a theme in AI chip procurement and how long an accelerator contract should run.
What This Should Change About Your IT Budget
Here's the part that actually costs money: cross-region replication, secondary-provider backups, and real failover testing all show up as line items, and they all get cut first when budget gets tight, because until this month, nobody could point to a concrete example of "region just doesn't come back." Now you can. Coverage of the aftermath noted that most customers in the affected regions had already relocated their workloads before the loss became permanent, using backups or standing up alternatives elsewhere — the ones who survived this cleanly are the ones who'd already paid for redundancy nobody thought they'd need. If you're building next year's infrastructure budget right now, this is your citation for why "resilience" deserves its own line rather than getting absorbed into "misc cloud spend." It's a lot easier to defend that number with a real incident attached to it than with a hypothetical.
The other budget conversation worth having is about where that resilience spend actually goes. A lot of IT budgets in 2026 are getting pulled toward AI infrastructure and agent tooling, because that's where the pressure from leadership is coming from, and "keep the lights on" line items lose that fight more often than they should. That is not an argument against investing in AI infrastructure, whose costs are covered in what running AI workloads costs once the invoice arrives. It is an argument that if cross-region backup testing gets deprioritized two years running because something flashier needed the budget, you've made a resilience decision without calling it one. Put it on the same slide as the AI roadmap and make someone actually choose.
Conclusion
AWS didn't do anything wrong here in the sense of breaking a promise — its own documentation has always said regional resiliency has limits, most people just never read that far down the page. The practical answer is straightforward: know the difference between AZ-level and region-level protection, verify your cross-region backups actually work instead of trusting the dashboard that says they're enabled, and get a real dollar figure in front of whoever signs off on infrastructure budget before the next region-scale event makes the decision for you. Protocol Wire keeps returning to the gap between a documented plan and a tested one.